01 / Reinforcement learning
Learning to navigate
DQN & Double DQN · Unity Banana
A controlled, three-seed comparison of value-based agents in a visual navigation environment.
Double DQN: 14.25 ± 1.63 · DQN: 12.05 ± 0.97
Data science · Machine learning · Systems
Hi, I’m Yanting — also Freya.
I study Data Science and Big Data Technology at CUHK-Shenzhen. I’m interested in machine learning and optimization, and enjoy turning ideas into practical tools.
Here is a selection of my experiments, research, and things I’ve built.
01Selected work
From agents learning in simulated worlds to tools people can use.
01 / Reinforcement learning
DQN & Double DQN · Unity Banana
A controlled, three-seed comparison of value-based agents in a visual navigation environment.
Double DQN: 14.25 ± 1.63 · DQN: 12.05 ± 0.97
02 / Reinforcement learning
DDPG · Unity Reacher
A shared policy learns to control 20 parallel robotic arms and keep each end effector on its target.
37.84 ± 0.71 evaluation score across three seeds
03 / Multi-agent learning
MADDPG · Unity Tennis
Two agents learn to keep a ball in play. Paired evaluation and cross-play explore coordination and partner generalization.
MADDPG: 1.559 · Independent DDPG: 1.285
04 / Natural language processing
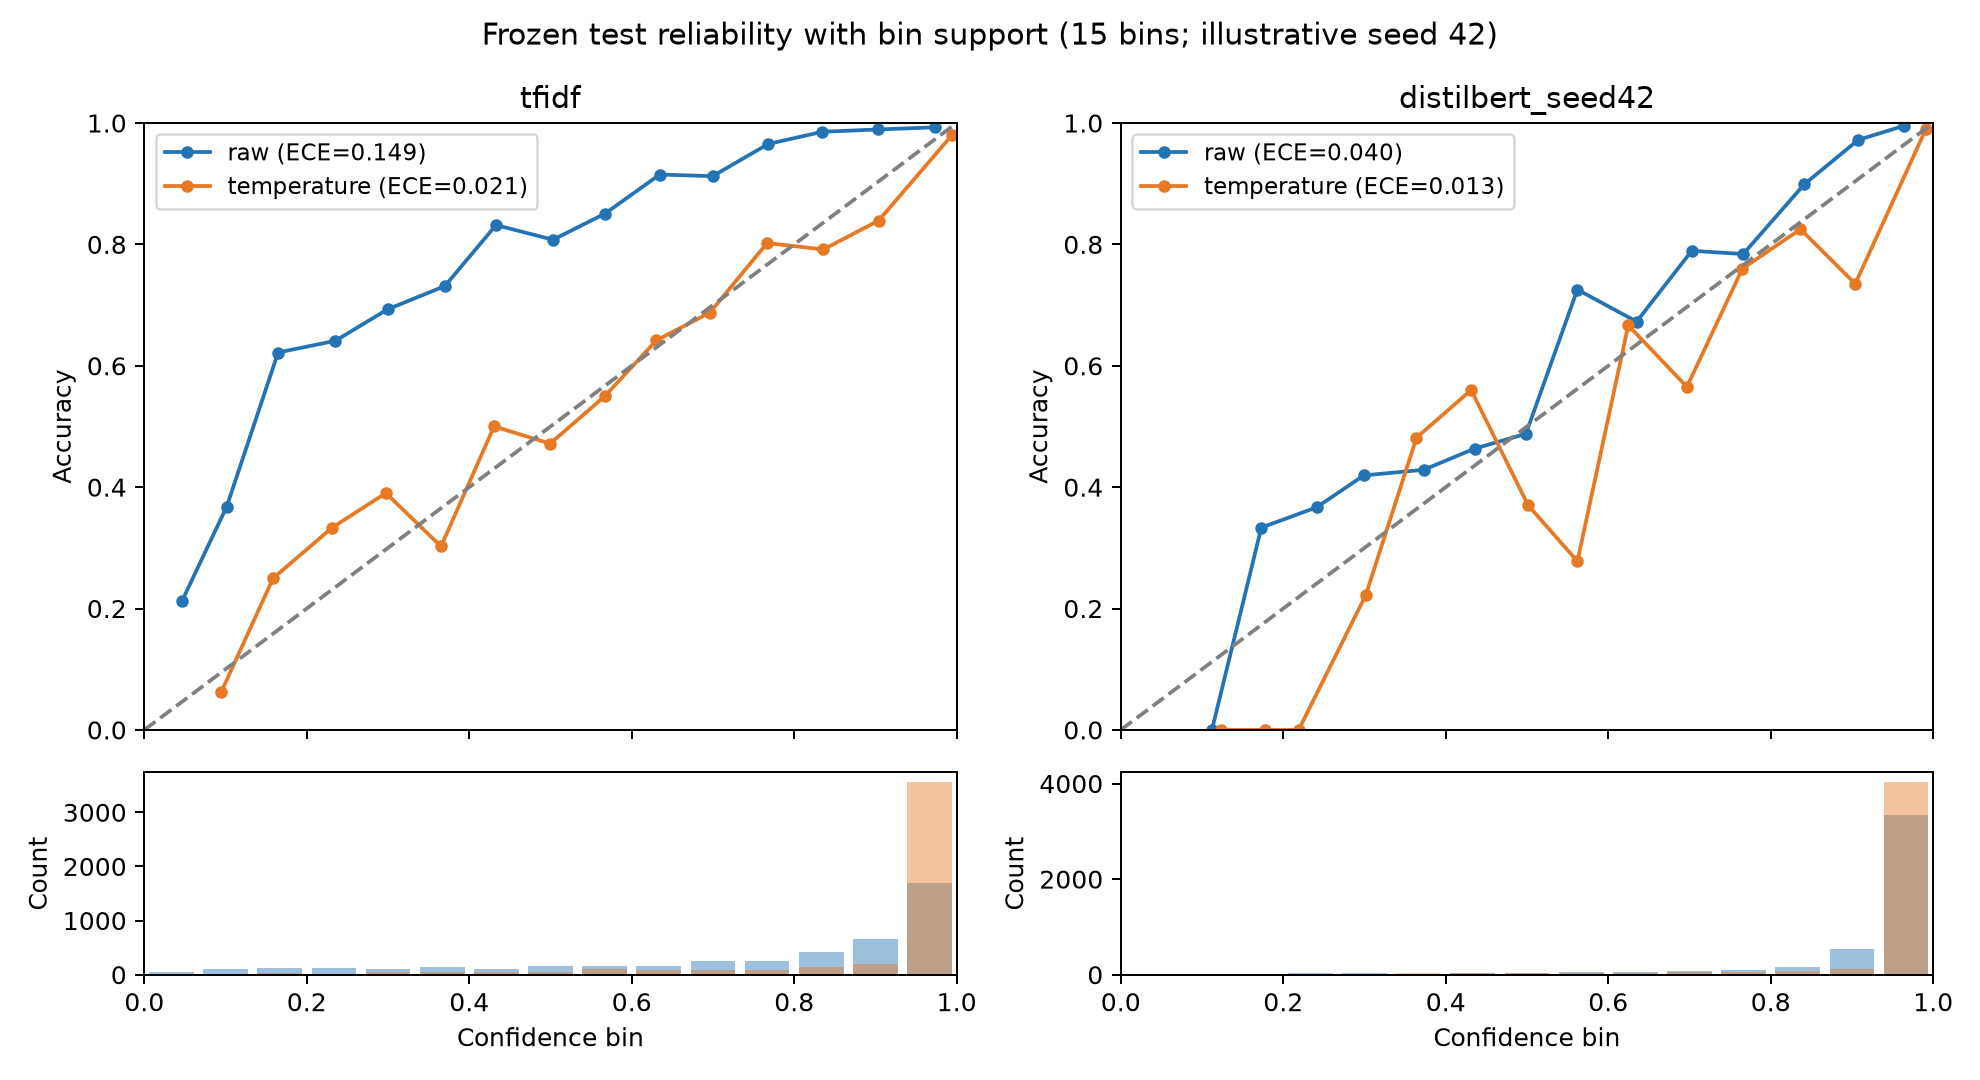
DistilBERT · Calibration & abstention
Studying the trade-off between calibrated confidence and out-of-scope rejection on CLINC150’s 150-intent task.
94.99% mean Macro-F1 · ECE 0.0434 → 0.0122
05 / AI engineering · Open source
Tauri · React · TypeScript · Rust
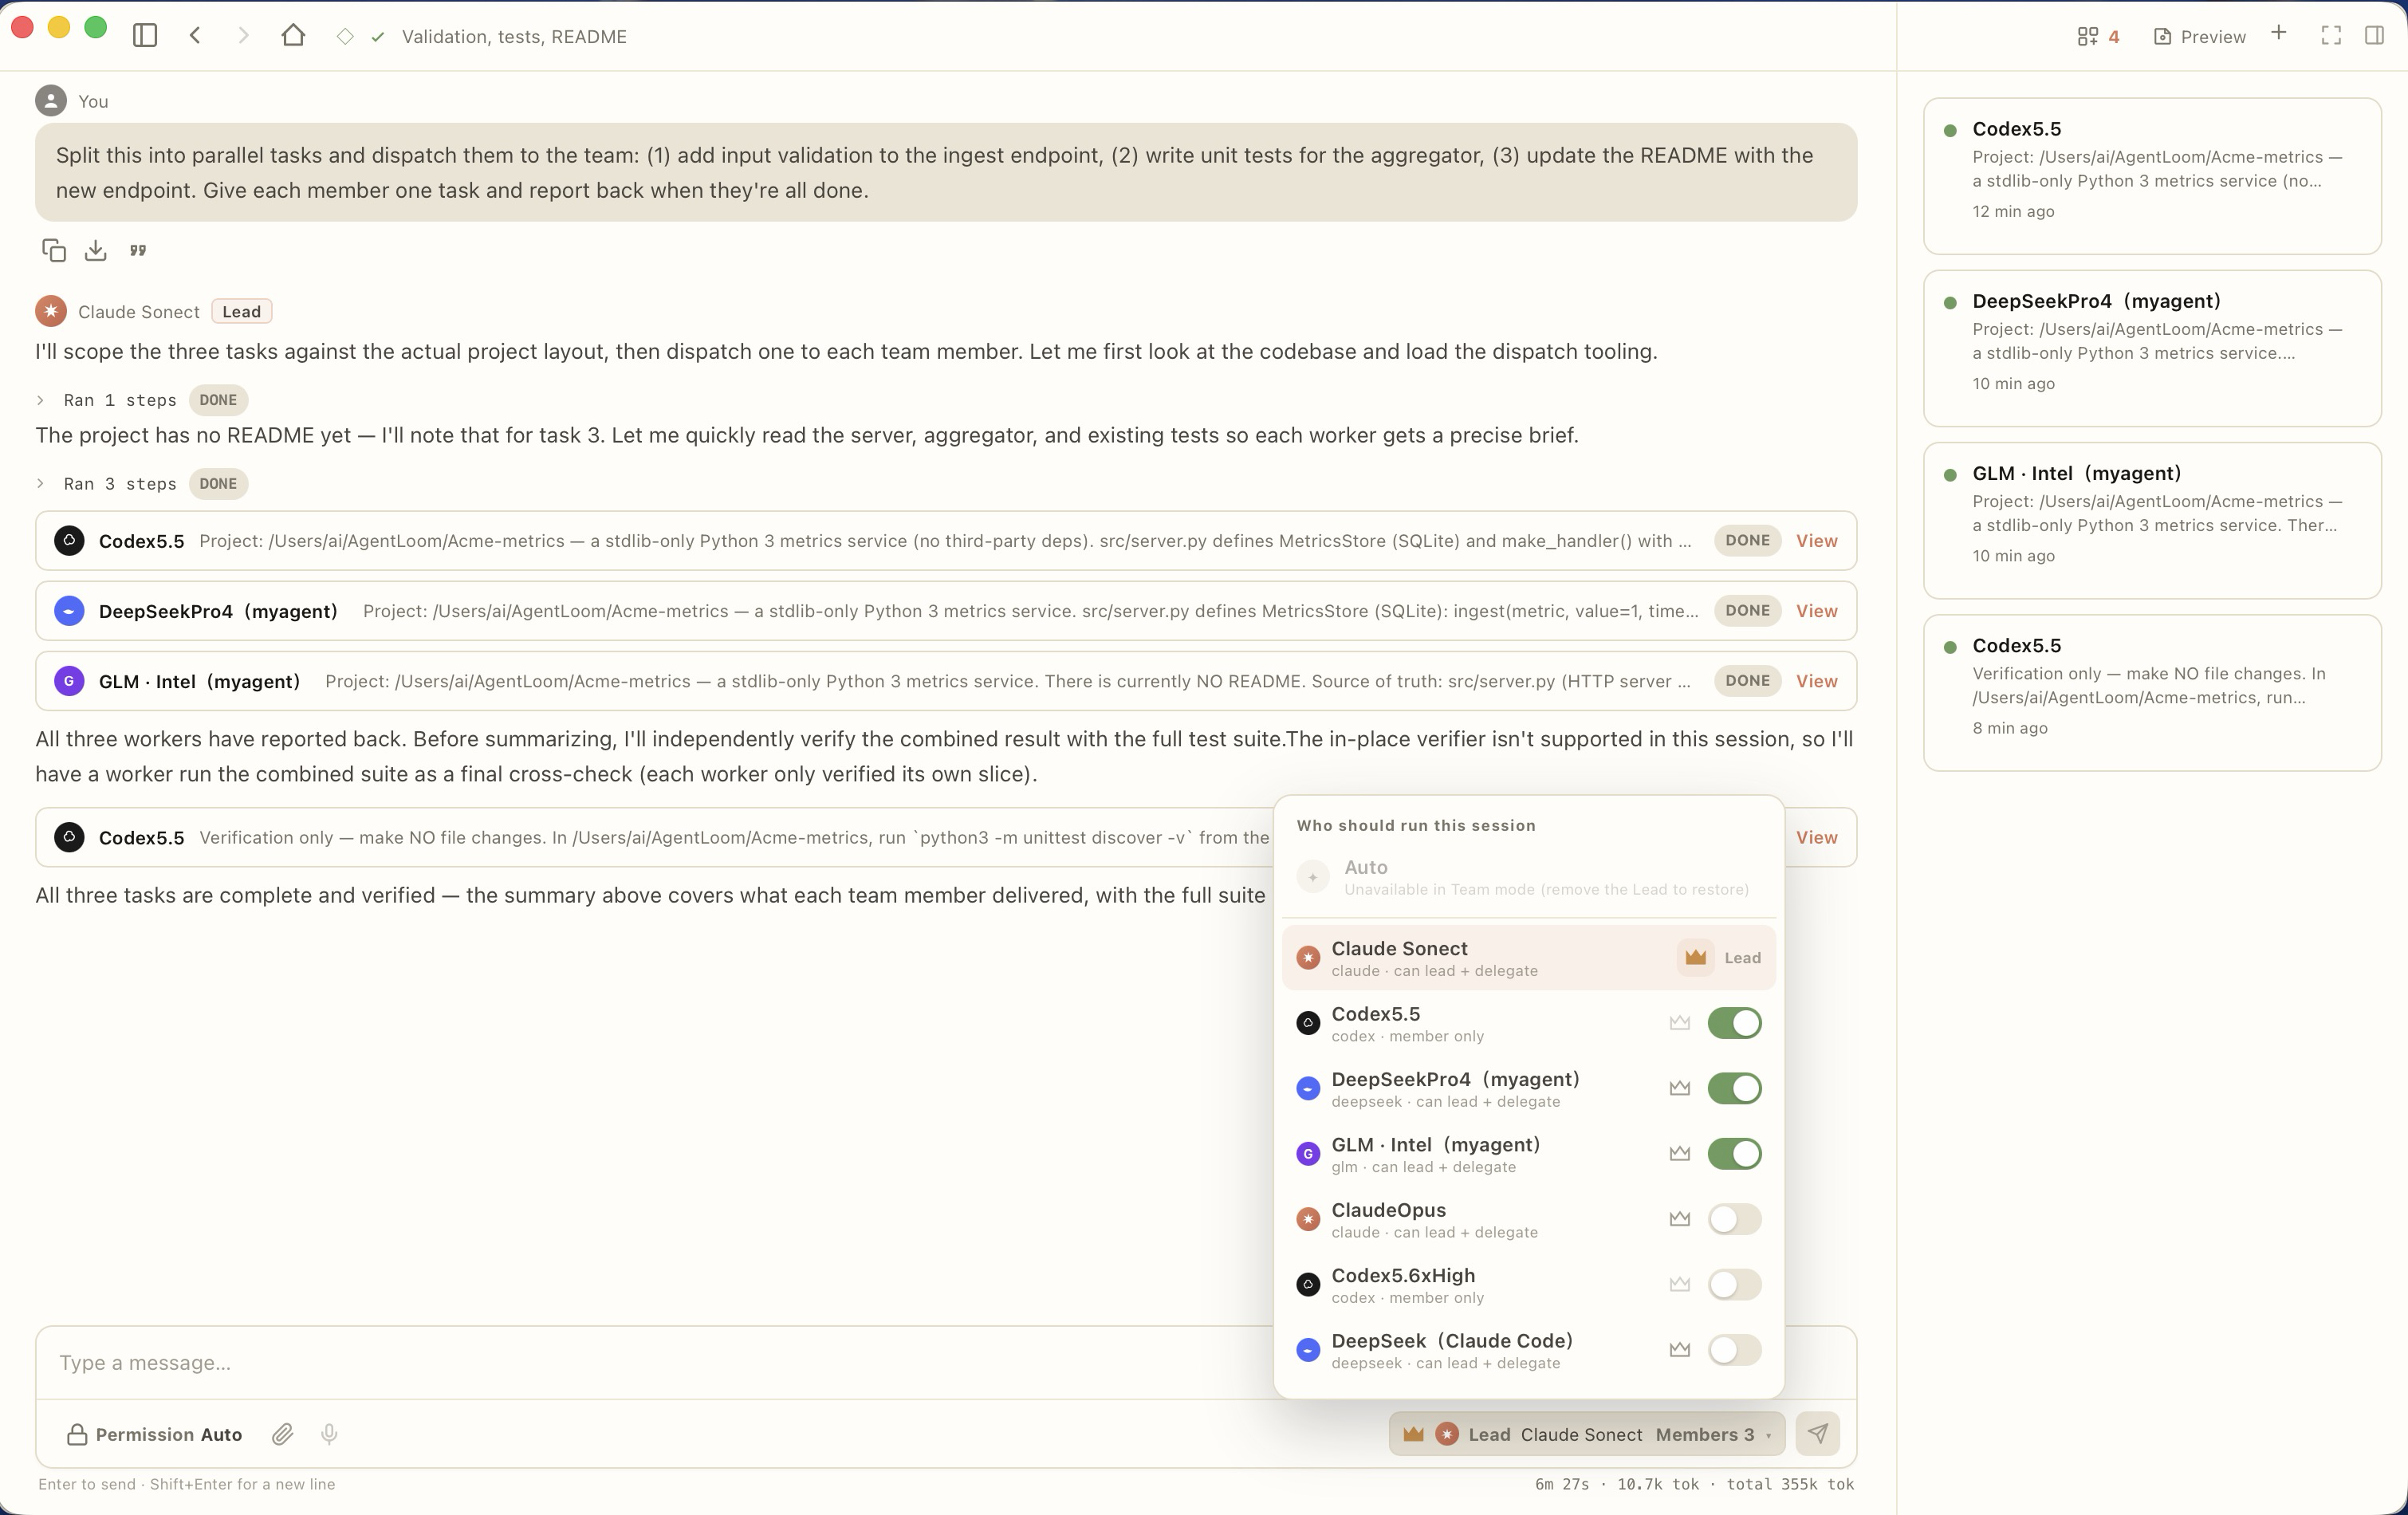
A local-first workspace for multiple coding agents, with shared context, parallel workflows, review, and rollback.
56.7% median resolution on a 30-task SWE-bench subset
06 / Product · Independent development
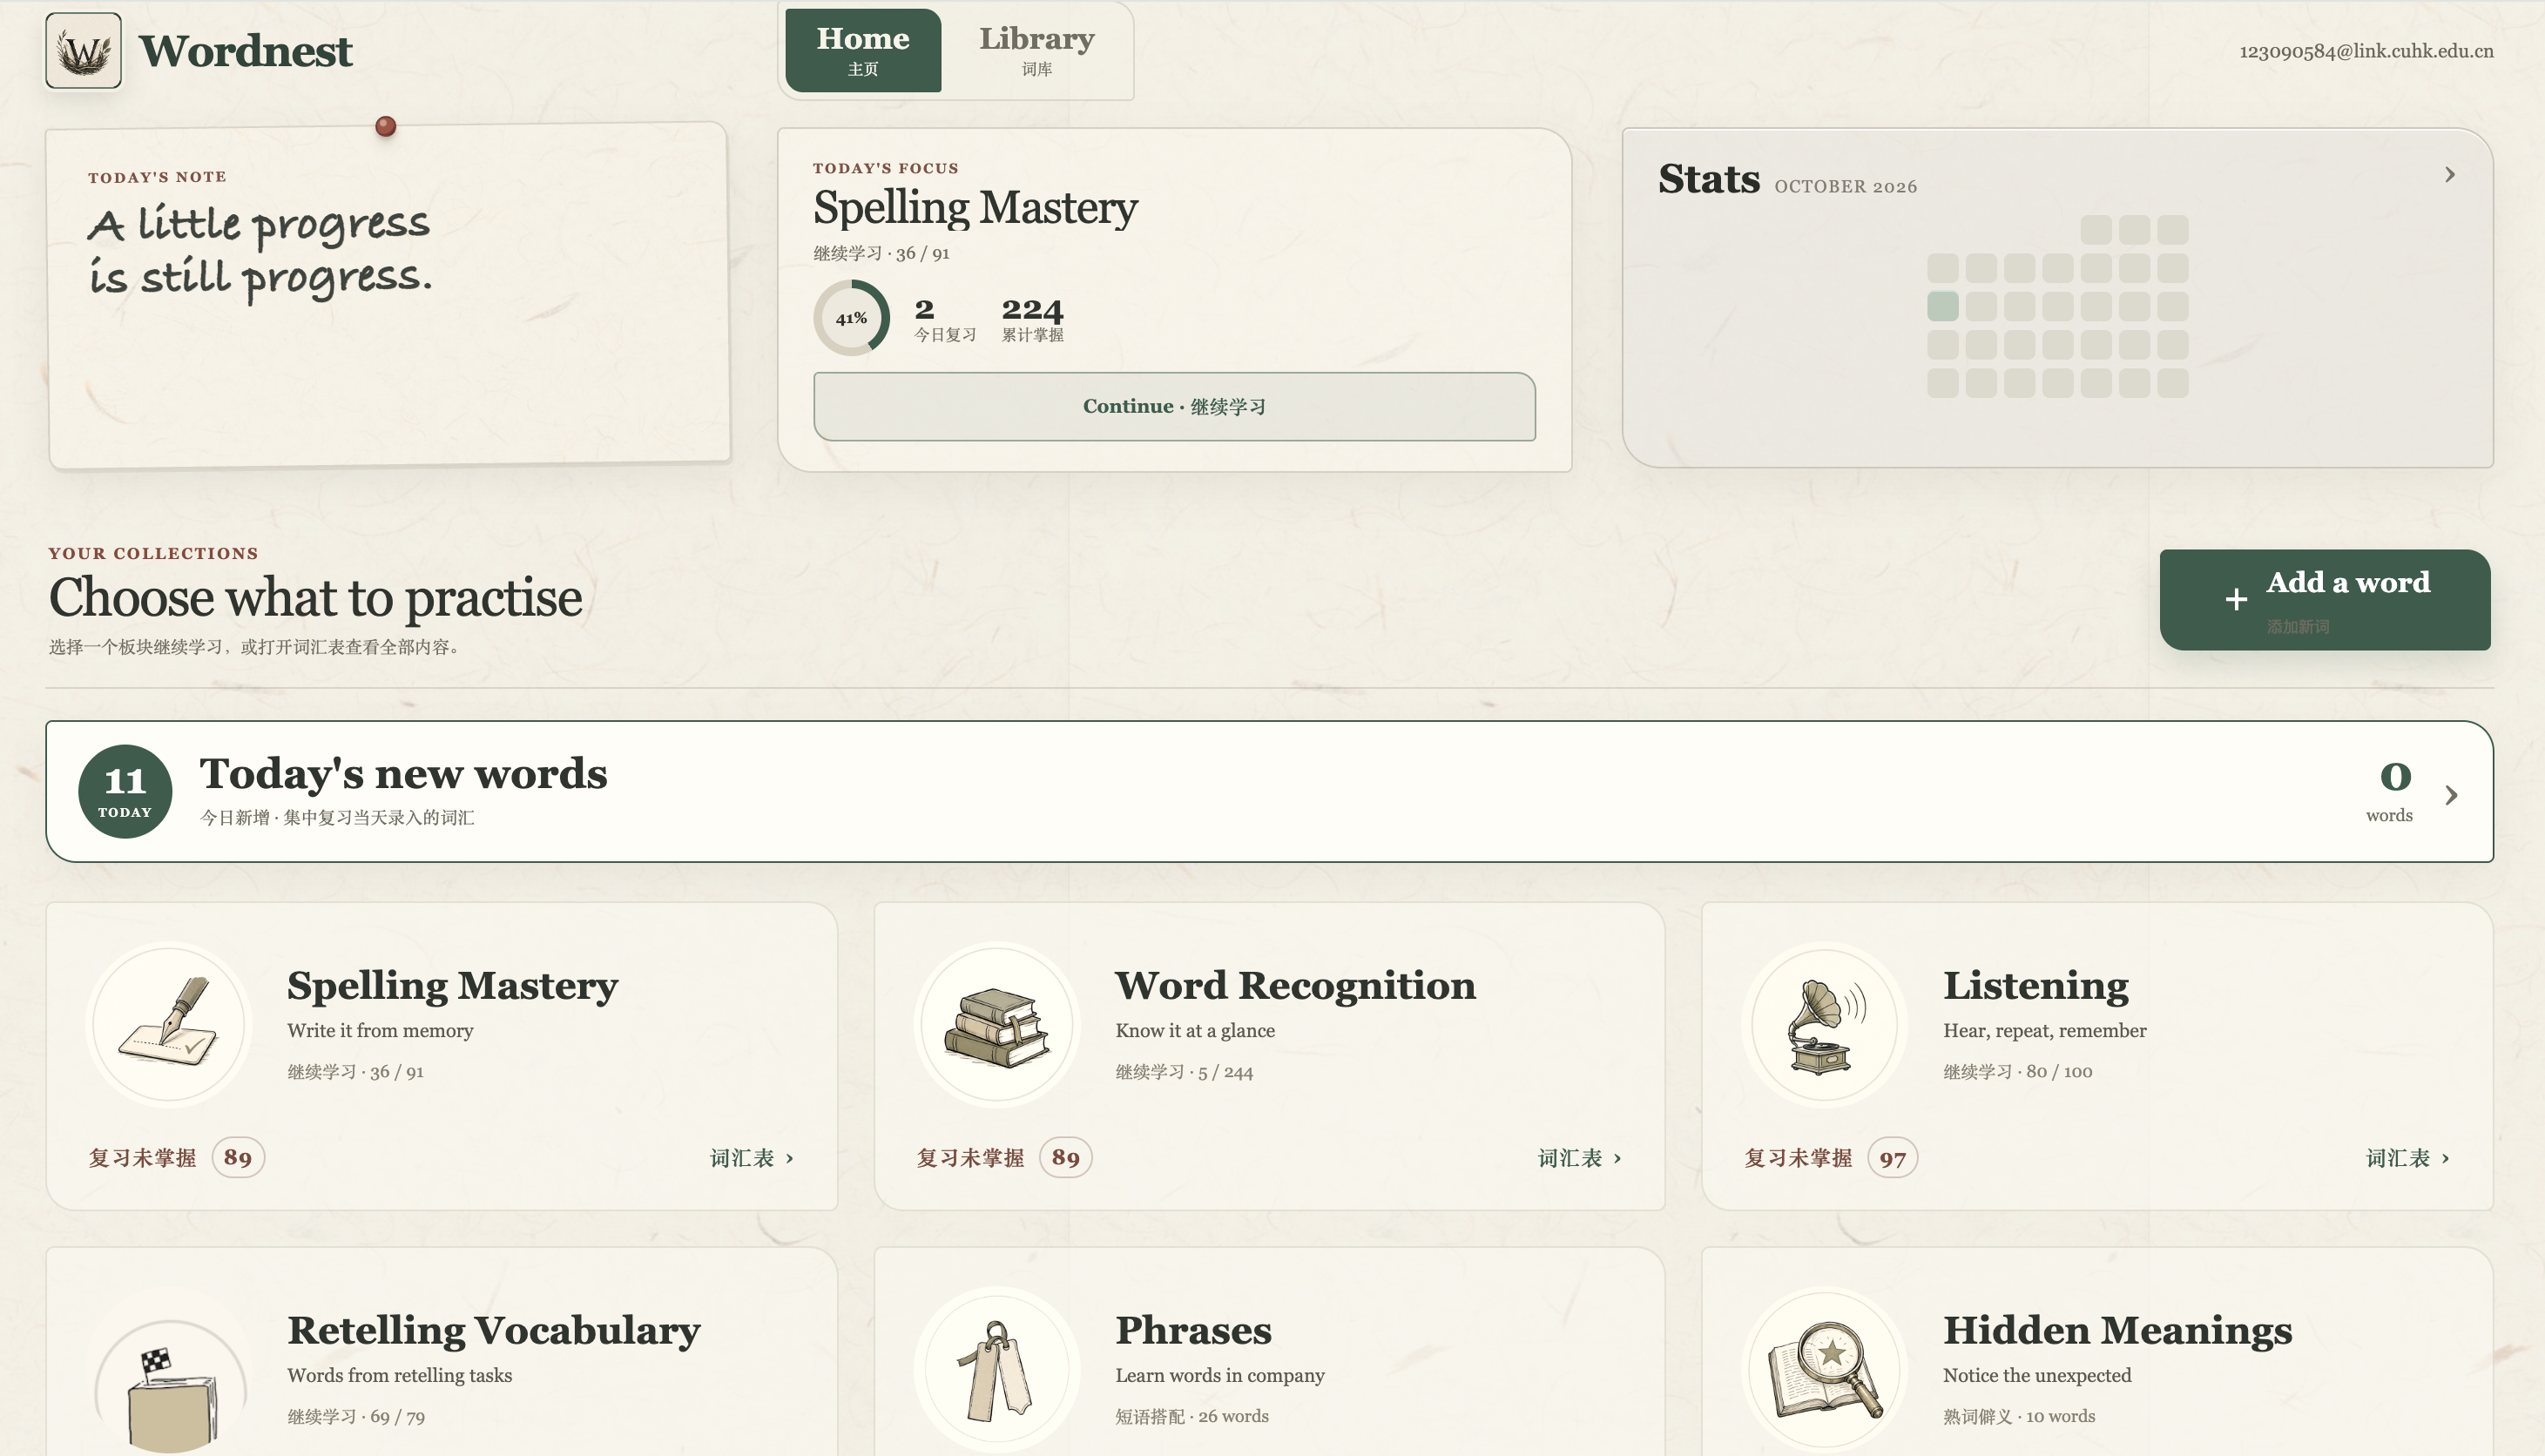
Personalized TOEFL vocabulary learning
A vocabulary platform with custom word lists, spelling practice, pronunciation, and progress that syncs across devices.
Independently designed, built, and launched
DRL results use frozen-policy evaluations. ± denotes population standard deviation across three seed-level means. See project notes for evaluation scope and limitations.
02Research
Oct 2025 — May 2026 / Research
Stochastic optimization · Academic–industry collaboration
A two-stage stochastic MILP for warehouse placement and truck–drone delivery. Reduced weighted service delay by 91% relative to an all-truck baseline and 88% relative to a fixed-location hybrid baseline.
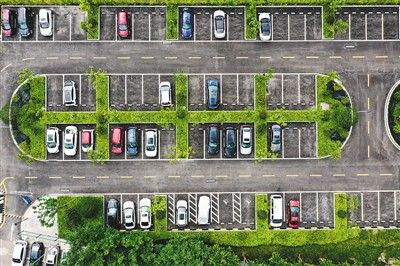
Dec 2024 — May 2025 / Research
Stochastic dynamic programming · Independent research
Modeled demand from 80,000 parking transactions, implemented a value-iteration solver, and ran 1,000+ Monte Carlo experiments. The policy achieved 73% of a perfect-information ILP upper bound in expected revenue.
03Experience
Feb — Jun 2026
AI Engineering Intern · Shipping Team
Built enterprise agent workflows, tool integrations, and logistics runbooks. A knowledge loop based on 550+ tickets and 112 runbooks achieved a 78% hit rate and reduced average handling time by 35%.
Jun — Aug 2025
Credit Modeling Intern · Housing & Consumer Finance
Prepared 200,000 loan records and compared response models for E-loan marketing. XGBoost achieved a test ROC-AUC of 0.807; the top-scoring 10% of customers had a 51.94% response rate and 4.61× lift.
04Beyond the screen
I enjoy painting, hiking, cycling, and team sports. I’ve also helped incoming students find their footing as a peer advisor and volunteered in family art therapy activities.
BSc, Data Science and Big Data Technology
CUHK-Shenzhen · 2023–2027
Dean’s List · 2023–2026
A selection of my drawings and paintings.